

Building a Self Serve Ingestion Framework for a Data Platform
On many data teams, every new source starts as a ticket. Someone in finance or product asks for a vendor feed, a data engineer writes a one off pipeline, and the backlog grows. A self serve ingestion framework changes that pattern. Source owners describe what they need in a short config file, and the platform turns that file into a working, monitored pipeline.
Decide what the config describes
A good config answers a few questions and nothing more. Where does the data come from. How often should it load. What is the primary key. Is the load a full refresh or incremental, and if incremental, which column marks new rows. Who owns the source and who gets alerted when it fails. Keep the format small and validate it in continuous integration, so a missing owner or an unknown connector type fails before anything reaches production.
Build a few connector types well
Most sources fall into a handful of patterns. Database tables, files dropped in object storage, REST APIs with pagination and event streams cover a large share of requests. Build one connector for each pattern, test it hard, and resist adding a new type for every edge case. When a source truly does not fit, a data engineer can still write a custom pipeline, but it should use the same logging, alerting and naming as the generated ones.
Make the defaults safe
Generated pipelines should land raw data in a predictable schema, add load timestamps, keep runs safe to repeat and apply retries with backoff. Schema changes in the source should raise a warning instead of silently dropping columns. Freshness checks should come from the schedule in the config, so owners get an alert when a load is late without writing anything extra.
Plan for ownership
Self serve only works if the people who add a source also keep it healthy. Route failures to the owner named in the config and send a weekly summary of stale or failing sources to the platform team. Remove sources nobody claims.
Where platform work appears in job listings
Teams that build frameworks like this often hire under platform titles. A search for platform on Data Engineer Jobs lists roles such as Senior Data Platform Engineer and Staff Database Engineer, each with the company, location and work model.
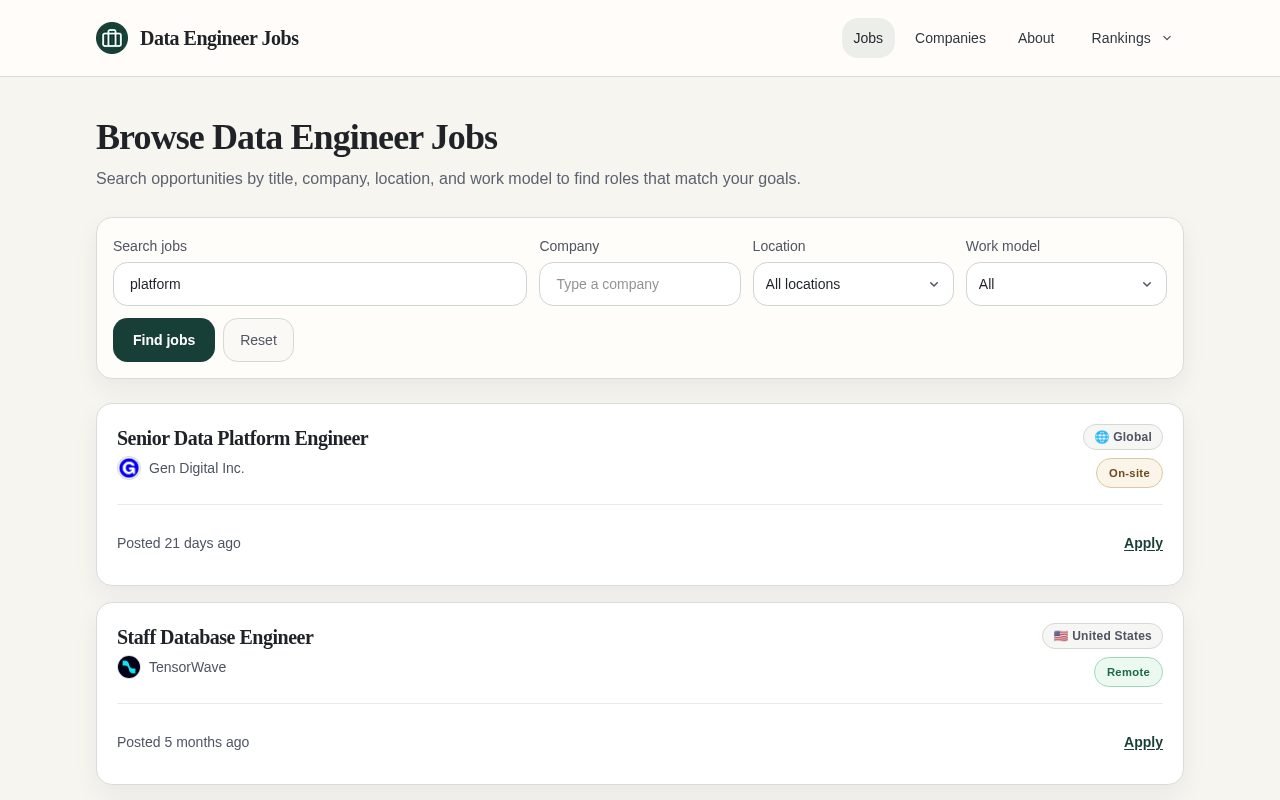
A platform keyword search on Data Engineer Jobs, with location and work model on each result.